Simulations - part I
DSCI 200
Katie Burak, Gabriela V. Cohen Freue
Last modified – 29 September 2026
\[
\DeclareMathOperator*{\argmin}{argmin}
\DeclareMathOperator*{\argmax}{argmax}
\DeclareMathOperator*{\minimize}{minimize}
\DeclareMathOperator*{\maximize}{maximize}
\DeclareMathOperator*{\find}{find}
\DeclareMathOperator{\st}{subject\,\,to}
\newcommand{\E}{E}
\newcommand{\Expect}[1]{\E\left[ #1 \right]}
\newcommand{\Var}[1]{\mathrm{Var}\left[ #1 \right]}
\newcommand{\Cov}[2]{\mathrm{Cov}\left[#1,\ #2\right]}
\newcommand{\given}{\ \vert\ }
\newcommand{\X}{\mathbf{X}}
\newcommand{\x}{\mathbf{x}}
\newcommand{\y}{\mathbf{y}}
\newcommand{\P}{\mathcal{P}}
\newcommand{\R}{\mathbb{R}}
\newcommand{\norm}[1]{\left\lVert #1 \right\rVert}
\newcommand{\snorm}[1]{\lVert #1 \rVert}
\newcommand{\tr}[1]{\mbox{tr}(#1)}
\newcommand{\brt}{\widehat{\beta}^R_{s}}
\newcommand{\brl}{\widehat{\beta}^R_{\lambda}}
\newcommand{\bls}{\widehat{\beta}_{ols}}
\newcommand{\blt}{\widehat{\beta}^L_{s}}
\newcommand{\bll}{\widehat{\beta}^L_{\lambda}}
\newcommand{\U}{\mathbf{U}}
\newcommand{\D}{\mathbf{D}}
\newcommand{\V}{\mathbf{V}}
\]
Attribution
Some of the material is based on content adapted from
Learning Objectives
Understand the mechanisms for generating and simulating data.
Contrast empirical and theoretical distributions.
Use simulations to approximate probability of events or distribution functions.
Use simulations to assess theoretical properties of random variables.
Explore the Central Limit Theorem (CLT) and Law of Large Numbers (LLN).
Write reproducible simulation code.
Interpret and reflect on simulation results using plots and summary statistics.
Last time: Simulations
Define the main steps of a simulation:
Define the process we want to simulate
Specify how randomness enters the process
Decide what to record from each run
Repeat the process many times
Summarize the results across runs
We used simulation to approximate two probabilities when randomness came from a physical event
Today, we’ll use simulations to study properties of estimators and generate randomness from sampling and using distributions!!
Sampling from a finite population
In lecture 3, we sampled from the wildfire population and compared population parameters with sample estimators.
Every time we select a new random sample we get a different estimate.
The Wildfire Population
library (tidyverse)library (infer)library (readr)<- read.csv ("https://raw.githubusercontent.com/UBC-DSCI/dsci-200/master/schedule/slides/data/wildfire.csv" ) head (wildfire)
  year fire_number current_size size_class latitude longitude     fire_origin
1 2006      PWF001         0.10          A    56.25   -117.18      Land Owner
2 2006      EWF002         0.20          B    53.61   -115.92 Fire Department
3 2006      EWF001         0.50          B    53.61   -115.59 Fire Department
4 2006      EWF003         0.01          A    53.61   -115.61        Industry
5 2006      PWF002         0.10          A    56.25   -117.05 Fire Department
6 2006      CWF001         0.20          B    51.15   -115.03 Fire Department
   general_cause responsible_group activity_class      true_cause
1       Resident          Resident          Grass  Permit Related
2     Incendiary            Others Lighting Fires Arson Suspected
3     Incendiary            Others Lighting Fires Arson Suspected
4     Incendiary            Others Lighting Fires Arson Suspected
5 Other Industry         Employees         Refuse  Permit Related
6       Resident          Resident   Unclassified     Unsafe Fire
      fire_start_date detection_agent_type detection_agent assessment_hectares
1 2006-04-02 12:00:00                  UNP             310                0.01
2 2006-04-03 12:10:00                  UNP             310                0.20
3 2006-04-03 12:15:00                  UNP             310                0.50
4 2006-04-03 12:10:00                  UNP             PUB                0.01
5 2006-04-03 17:00:00                  UNP             LFS                0.10
6 2006-04-02 14:25:00                  UNP             310                0.20
  fire_spread_rate fire_type fire_position_on_slope
1              0.0   Surface                   Flat
2              0.0   Surface              Lower 1/3
3              0.0   Surface                 Bottom
4              0.0   Surface                   Flat
5              0.1   Surface                   Flat
6              0.0   Surface                   Flat
  weather_conditions_over_fire temperature relative_humidity wind_direction
1                        Clear          18                10             SW
2                        Clear          12                22             SW
3                        Clear          12                22             SW
4                        Clear          12                22             SW
5                        Clear           6                37             SW
6                        Clear          11                32              S
  wind_speed fuel_type initial_action_by ia_arrival_at_fire_date ia_access
1          2       O1a        Land Owner                    <NA>   Unknown
2         10       O1a   Fire Department                    <NA>   Unknown
3         10       O1a   Fire Department                    <NA>   Unknown
4         10       O1b          Industry                    <NA>   Unknown
5          2   Unknown   Fire Department                    <NA>   Unknown
6         20       O1b   Fire Department                    <NA>   Unknown
  fire_fighting_start_date fire_fighting_start_size bucketing_on_fire
1                     <NA>                     0.02           Unknown
2                     <NA>                     0.02           Unknown
3                     <NA>                     0.02           Unknown
4                     <NA>                     0.02           Unknown
5                     <NA>                     0.02           Unknown
6                     <NA>                     0.02           Unknown
        first_bh_date first_bh_size       first_uc_date first_uc_size
1 2006-04-02 22:00:00          0.01 2006-04-02 22:00:00          0.01
2 2006-04-03 13:20:00          0.20 2006-04-03 13:20:00          0.20
3 2006-04-03 13:23:00          0.50 2006-04-03 13:23:00          0.50
4 2006-04-03 14:08:00          0.01 2006-04-03 14:08:00          0.01
5 2006-04-03 19:57:00          0.10 2006-04-03 20:19:00          0.10
6 2006-04-02 16:00:01          0.20 2006-04-02 16:00:01          0.20
  first_ex_size_perimeter
1                    0.10
2                    0.20
3                    0.50
4                    0.01
5                    0.10
6                    0.20
We’ll focus on the numerical variable temperature
Population parameters for temperature
|> summarise (mean_temp = mean (temperature, na.rm = TRUE ),med_temp = median (temperature, na.rm = TRUE ),var_temp = var (temperature, na.rm = TRUE ),sd_temp = sd (temperature, na.rm = TRUE ),min_temp = min (temperature, na.rm = TRUE ),max_temp = max (temperature, na.rm = TRUE )
  mean_temp med_temp var_temp  sd_temp min_temp max_temp
1   17.8787       19 60.13478 7.754662      -39       45
A random sample and sample estimates
set.seed (200 )<- wildfire |> rep_sample_n (size = 100 )<- wildfire_sample$ temperaturec (x_bar = mean (temperature_rv, na.rm = TRUE ), s = sd (temperature_rv, na.rm = TRUE ))
    x_bar         s
17.118681  7.236496
Temperature as a random variable
Every time we take a new sample, the values of temperature change.
temperature is a random variable and randomness comes from sampling!
Any statistic of temperature becomes a random variable as well.
for example, the mean temperature (\(\bar{x}\) ) is a random variable
The changes in point estimates across samples is called sampling variability
Standard errors
The standard error of an estimator measures how much the sample estimate (like the mean) is expected to vary across different random samples.
In lecture 3 we said that the standard error of the sample mean is given by:
\[SE(\bar{x}) = \frac{\sigma}{\sqrt{n}}\] and the population parameter \(\sigma\) can be estimated with the sample standard deviation \(s\) .
Let’s build a simulation
Let’s use simulation to study the variability of the sample mean (standard error) when sampling from a finite population.
Define the process we want to simulate
Specify how randomness enters the process
Decide what to record from each run
Repeat the process many times
Summarize the results across runs
iClicker 1: simulation design
Which of the following options best describes a simulation study?
A. Drawing a single sample from the population and computing the mean of temperature in the sample
B. Drawing many samples from the population and computing the mean of temperature in each sample
C. Computing the mean of temperature from the full population
D. Generating temperature values from a Normal distribution and computing its mean
in R
Take a random sample of size \(n = 7000\)
Compute the sample mean temperature
Repeat this 1000 times
set.seed (200 )<- wildfire |> select (temperature) |> drop_na () # sample size <- 7000 # population size <- nrow (pop_temp_complete)# number or replicates <- 1000 <- pop_temp_complete |> rep_sample_n (size = sample_size, reps = n_reps) |> group_by (replicate) |> summarise (sample_mean_temp = mean (temperature, na.rm= TRUE ))
We now have a list of 1000 sample mean temperatures!
Summarize
We can use the list of sample estimates to study the sampling variability.
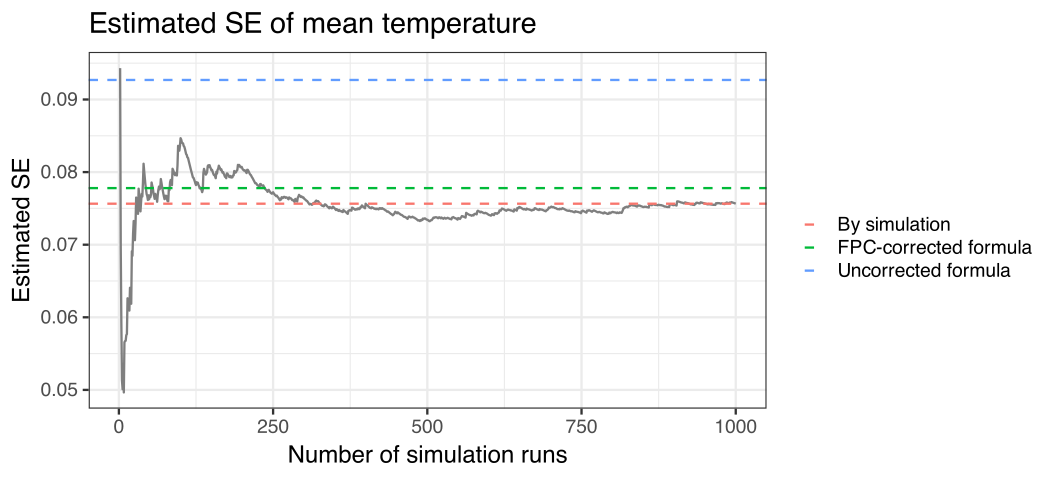
Let’s approximate the SE computing the standard deviation of the sample estimates
#SE of X_bar by simulation <- sd (sample_mean_reps$ sample_mean_temp))#SE of X_bar by formula <- sd (pop_temp_complete$ temperature)/ sqrt (sample_size))
Something seems off ….
Sampling from a finite population
When sampling without replacement from a finite population observations are not independent.
The variability of the sample mean is smaller than in model-based sampling.
This reduction in variability is captured by the finite population correction (FPC):
\[ SE(\bar{x}) = \frac{\sigma}{\sqrt{n}}*\sqrt{1-\frac{n}{N}}
\]
where \(N\) and \(n\) are the population and the sample sizes, respectively.
library (ggplot2)library (tidyr)<- sapply (seq_along (sample_mean_reps$ sample_mean_temp),function (k) sd (sample_mean_reps$ sample_mean_temp[1 : k])<- data.frame (runs = seq_along (sample_mean_reps$ sample_mean_temp),se_mean_temp = cum_sd<- tidyr:: pivot_longer (- runs,names_to = "event" ,values_to = "estimate" <- sqrt (1 - (sample_size / pop_size))<- se_formula * fcp<- data.frame (se = c (se_simulation, se_corrected_fpc, se_formula),method = c ("By simulation" , "FPC-corrected formula" , "Uncorrected formula" )<- ggplot (sample_mean_temp_long, aes (x = runs, y = estimate, color = event)) + geom_line () + geom_hline (data = ref_lines,aes (yintercept = se, color = method),linetype = "dashed" + scale_color_manual (values = c ("By simulation" = "#F8766D" , "FPC-corrected formula" = "#00BA38" , "Uncorrected formula" = "#619CFF" + labs (x = "Number of simulation runs" ,y = "Estimated SE" ,color = "" ,title = "Estimated SE of mean temperature"
Generating values from a distribution
Another way of generating randon numbers is using well-known probability distributions like the Normal, Poisson, and binomial.
in R
rnorm: generate random Normal variates
arguments: n (sample size), mean and sd
rpois: generate random Poisson variates
arguments: n, lambda (rate)
runif: generate random Uniform variates
arguments: n, min, max (interval)
rbinom: generate random binomial variates
Example
 [1] 2.145213 3.497129 4.741089 2.368110 4.608956 4.584238 3.140547 3.082035
 [9] 2.058829 3.558137
   Min. 1st Qu.  Median    Mean 3rd Qu.    Max.
  2.059   2.547   3.319   3.378   4.328   4.741
Everytime we run this code, it generates new values
Setting the seed
set.seed (200 )runif (5 , 2 , 5 )
[1] 3.601317 3.751295 3.768735 4.073120 4.001994
# changing the sequence set.seed (200 )runif (5 , 2 , 5 )
[1] 3.601317 3.751295 3.768735 4.073120 4.001994
Key takeaways
Simulations can be used to:
approximate probabilities,
study properties of estimators,
approximate distributions
Randomness can be introduced using code that:
mimics physical processes
randomly select outcomes from a finite population
generates random values from a distribution